Over the past few years, large language models have moved quickly from writing assistants to research tools.
Researchers now use them to classify thousands of documents, measure sentiment from text, extract information from corporate disclosures, summarize policy positions, generate hypotheses, and even predict economic or political outcomes.
At first glance, this seems like an extraordinary productivity gain.
Tasks that once required hundreds of hours of manual coding can now be completed in minutes. Unstructured text can suddenly become structured data. Entire archives of news articles, earnings calls, regulatory documents, or survey responses can be analyzed at a scale that would previously have been impractical.
But there is a deeper methodological question hiding underneath all of this:
When an LLM gives us an answer, what exactly are we observing?
Are we observing reasoning?
Or are we observing memory?
That distinction may determine whether AI becomes a genuinely transformative research instrument—or simply a more sophisticated source of measurement error.
This is the central question explored in Large Language Models: An Applied Econometric Framework by Jens Ludwig, Sendhil Mullainathan, and Ashesh Rambachan, which examines how LLM-generated outputs can be incorporated into empirical research without compromising scientific validity.
The first problem: prediction may not actually be prediction
Suppose we ask an LLM to read a piece of financial news and predict whether a company's stock price will rise.
The model performs extremely well.
It is tempting to conclude that the model has learned something meaningful about financial markets.
But there is another possibility.
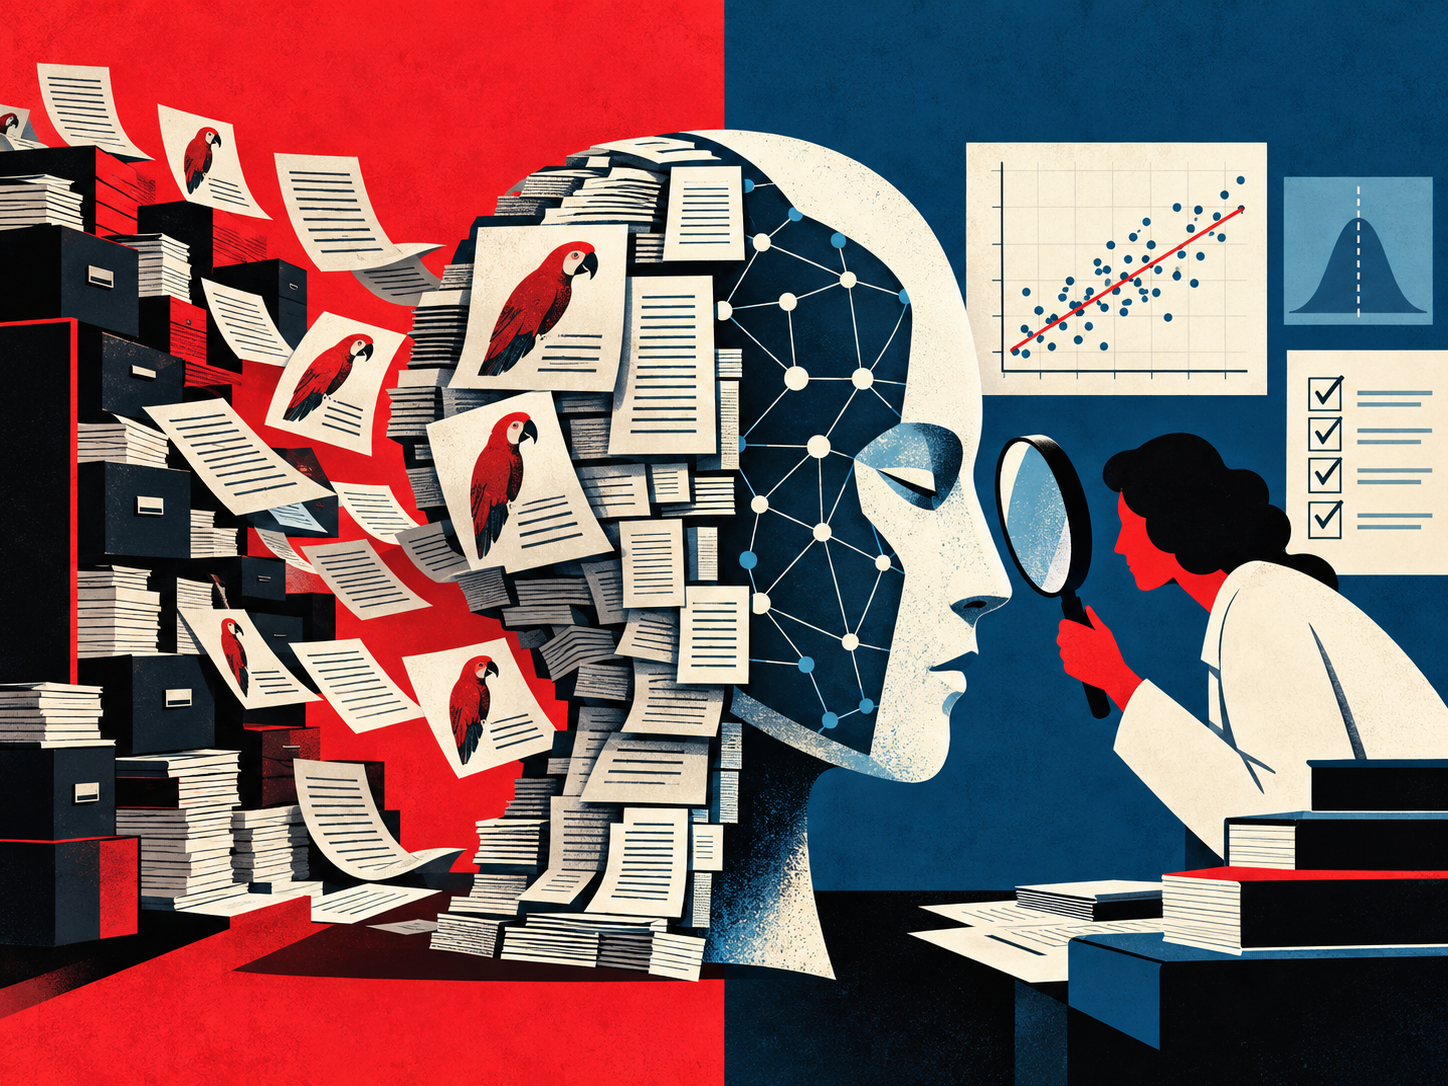
The model may have encountered the article—or information about what happened afterward—during training.
In other words, what looks like forecasting may actually be retrieval disguised as prediction.
The paper highlights how serious this problem can become. In one example involving Congressional legislation, GPT-4o achieved prediction accuracy above 91%. Yet when researchers provided only the first half of certain bills, the model was able to reproduce hundreds of them word-for-word, suggesting that some of the apparently impressive predictive performance may have been contaminated by memorization.
A similar problem appears in financial research.
When a model trained on internet-scale data is asked to analyze historical information, researchers may have no reliable way of knowing whether the model has seen information from the future relative to the event being studied.
This creates a form of look-ahead bias.
The research problem is therefore not simply whether an LLM produces accurate predictions.
The more important question is:
Could the model have known the answer already?
If the answer is yes—or if we cannot confidently rule it out—then impressive accuracy may tell us very little about the model's ability to generalize to genuinely unseen events.
For empirical researchers, that is a major distinction.
A forecasting system that performs well because it has indirectly seen the future is not a forecasting system.
The second problem is more subtle: turning language into data
There is another way researchers increasingly use LLMs.
Instead of asking the model to predict the final outcome, they use it to measure something hidden inside text.
Imagine analyzing thousands of central-bank speeches.
An LLM could classify each speech as hawkish or dovish.
Or researchers might use models to quantify management sentiment in earnings calls, identify topics in regulatory documents, measure political positioning, or extract expectations from survey responses.
The resulting AI-generated score then becomes a variable inside a regression.
This is enormously useful.
It is also where classical econometric problems return in a new form.
The LLM is effectively acting as a measurement instrument.
And measurement instruments make errors.
The paper argues that those errors are not necessarily random. LLM outputs can change depending on the model version, the wording of the prompt, or seemingly minor implementation choices. More importantly, those errors may correlate systematically with the economic variables researchers are trying to study.
That means the problem is not simply that an AI-generated label might occasionally be wrong.
The problem is that the errors themselves can bias the estimated relationship.
In experiments summarized in the report, seemingly innocuous changes in prompts or model generations can materially alter empirical estimates—and in some cases even change their sign.
For anyone who has worked with econometrics, this should sound familiar.
AI does not eliminate the measurement-error problem.
It simply introduces a new and much more scalable version of it.
The solution is surprisingly old-fashioned
One of the most useful conclusions from the paper is that rigorous use of AI does not necessarily require trusting AI more.
It requires better research design.
For prediction tasks, researchers need to establish that the model could not have encountered the evaluation data during training. That may mean using models with known training cut-off dates, evaluating on documents created after those dates, or using confidential datasets that were never publicly available.
For measurement tasks, the recommended approach looks surprisingly familiar to traditional empirical research:
keep a human-labeled validation sample.
Rather than manually labeling an entire dataset, researchers can label a relatively small random subset and use it to measure systematic differences between human judgments and LLM outputs.
The LLM provides scale.
Humans provide the benchmark.
Statistics provide the correction.
The framework described in the paper uses the validation sample to estimate the systematic error in AI-generated measurements and then correct the downstream estimate accordingly.
This creates an interesting division of labor.
AI does not replace human judgment.
Instead, human judgment becomes the calibration layer for AI at scale.
That may turn out to be one of the most important patterns in applied AI more broadly.
This matters far beyond economics
Although the paper is framed around econometric research, the underlying issue applies to almost anyone using AI to convert unstructured information into decisions.
Consider equity research.
An analyst could use an LLM to process thousands of earnings-call transcripts and generate management-confidence scores.
A strategy team could classify thousands of customer reviews into demand drivers.
A government agency could analyze public comments to identify emerging policy concerns.
A consulting team could use AI to code hundreds of interview transcripts.
In each case, the same temptation appears:
because the model can process far more information than a human team, its output begins to feel objective.
But scale and objectivity are different things.
A model can systematically classify one type of language differently from another. It can respond differently after a version update. It can embed information from its training data that researchers did not intend to introduce.
And because these systems are extremely capable, those problems can be harder—not easier—to notice.
The danger is not always an obviously bad answer.
Sometimes the more dangerous outcome is a plausible answer with an invisible methodological flaw.
AI may change research, but it does not change the rules of evidence
There is a broader lesson here about how we should think about generative AI.
Much of today's discussion focuses on whether models are intelligent enough to perform a task.
But for serious analytical work, that may be the wrong standard.
The relevant question is not simply:
“Can the model do this?”
It is:
“Can I design a process in which the model's output can be trusted?”
Those are very different questions.
An LLM can be imperfect and still be extremely valuable if its errors can be measured and corrected.
Conversely, an extraordinarily capable model can produce scientifically unreliable results if researchers cannot distinguish genuine inference from memorization or systematic bias.
That shifts the discussion away from model intelligence and toward institutional and analytical design.
The future of AI-assisted research may therefore look less like replacing researchers with autonomous models and more like creating systems in which machines perform the high-volume work while humans retain responsibility for validation, identification, and interpretation.
The report summarizes this idea particularly well: LLMs should amplify human insight, while scientific rigor remains the constraint around how their outputs are used.
And perhaps that is the more useful way to think about AI in research.
The breakthrough is not that we can finally stop checking the machine.
It is that we can now analyze far more than before—provided we know what still needs to be checked.